01 · What is this about?choice
BillingBilling88%
Technical support3%
Account5%
Other4%
LAB / 01 · TYPED DECISIONS
Jev returns a category, score, or probability for questions about your input. Your application rules decide what to do with those answers. Try a customer message example, then explore routing, context selection, and evidence checks.
Independent lab · No account required · Synthetic samples included
LAB / 02 · TRY JEV
Start with the prepared message and run it as-is, or replace it with your own. No account is required.
YOUR INPUT
A customer message
JEV WILL ANSWER
What is this customer message primarily about? If several topics appear, choose the one tied to the customer’s main request.
choiceHow urgent is the customer’s need, based only on the impact and timing stated in the message?
scoreDoes the customer still have an unresolved problem or an explicit request that needs a follow-up?
booleanJEV’S ANSWERS
Category, urgency, and follow-up
Probability-weighted rubric position, not a percentage or confidence score.
No action is needed.
A routine question or low-impact request.
A problem affects use, but no clear deadline or major blockage is stated.
Core work is blocked or a near-term deadline is stated.
A severe outage, active loss, or similarly serious interruption is happening now.
Jev returns typed signals your support system can use. This example does not send a reply or create a ticket.
PROVIDER CONFIDENCE · SEPARATE FROM ANSWER PROBABILITY
Message category 79%Urgency 62%{
"origin": "illustrative-example",
"input": {
"message": "I was charged twice for this month’s subscription. Could you check the second charge and refund it?"
},
"questions": {
"category": {
"type": "choice",
"instructions": "What is this customer message primarily about? If several topics appear, choose the one tied to the customer’s main request.",
"criteria": {
"billing": "Charges, payments, invoices, refunds, pricing, or subscription billing.",
"technical-support": "A product feature is broken, failing, unavailable, or behaving unexpectedly.",
"account": "Sign-in, password, profile, access, permissions, or account administration.",
"other": "The main topic does not fit billing, technical support, or account administration."
}
},
"urgency": {
"type": "score",
"instructions": "How urgent is the customer’s need, based only on the impact and timing stated in the message?",
"criteria": [
"No action is needed.",
"A routine question or low-impact request.",
"A problem affects use, but no clear deadline or major blockage is stated.",
"Core work is blocked or a near-term deadline is stated.",
"A severe outage, active loss, or similarly serious interruption is happening now."
]
},
"needsFollowUp": {
"type": "boolean",
"instructions": "Does the customer still have an unresolved problem or an explicit request that needs a follow-up?",
"criteria": {
"true": "The message contains an unresolved issue, unanswered question, or explicit request.",
"false": "The message says the matter is resolved or contains no request requiring a response."
}
}
},
"answers": {
"category": {
"type": "choice",
"choice": "billing",
"probabilities": {
"billing": 0.88,
"technical-support": 0.03,
"account": 0.05,
"other": 0.04
}
},
"urgency": {
"type": "score",
"score": 2.4,
"probabilities": {
"0": 0.01,
"1": 0.08,
"2": 0.48,
"3": 0.36,
"4": 0.07
}
},
"needsFollowUp": {
"type": "boolean",
"probability": 0.97
}
},
"providerConfidence": {
"category": 0.79,
"urgency": 0.62
},
"run": null
}LAB / 03 · WHAT IT IS
Many applications need a specific answer: a category, a score, or an estimate of whether something is true. A chat model can answer in prose, but the application then has to extract the value it needs.
With Jev, you provide an input — such as a ticket, message, draft, or proposed tool call — and define the questions it should answer. Jev returns values in the requested answer types, without a paragraph to parse.
You can inspect the returned values and probabilities. Your own code decides whether to act, ask for review, or do nothing.
LAB / 04 · THE THREE QUESTIONS
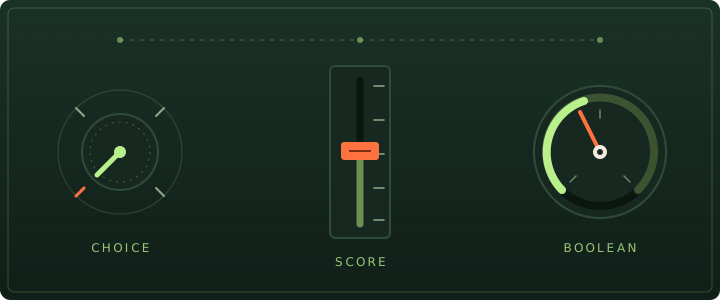
Ask multiple questions about the same input in one call.
Pick one option from a named set you define — which team owns this ticket, which tool the agent should reach for next, which of your routes fits. You get the selection plus a probability across every candidate.
Up to 255 options.
Place the state on an ordered rubric you write out in plain language, from lowest to highest. Useful for severity, urgency, risk, or quality. The result can land between levels, because it is a probability-weighted position rather than a single pick.
Rubrics of 2–10 levels.
Estimate how likely a statement is to be true. You get a number between 0 and 1, not a flat yes — 0.97 and 0.51 mean very different things to a policy, and collapsing them to true throws away the part that mattered.
Probability, not a verdict.
LAB / 05 · HOW IT WORKS
Send the data Jev should evaluate and define the choices, scoring scale, or yes-or-no questions you need answered.
Look at the selected value and its probabilities separately from any confidence information returned by the provider.
Set thresholds in your code. You can change whether an answer triggers an action or human review without running the model again.
LAB / 06 · FIT
Jev is useful when an application repeatedly needs to choose from defined options, score an input, or estimate a yes-or-no answer. Test its answers against your own examples before using them in a workflow.
LAB / 07 · EXAMPLES
IDEA / REVIEW
Enter a startup idea to see which customer, problem, and differentiation claims still need evidence. This does not predict success.
DRAFT / REVIEW
Enter a draft to see scores for tone and clarity, then compare versions. The tool does not rewrite your text.
AGENT / SIMULATOR
Choose a goal in a fictional settings app and watch Jev select the next allowed action, for up to six steps.
TASK / ROUTING
Enter a task to see which route Jev selects and whether your app rules allow that route or require review.
CONTEXT / SELECTION
Enter a task and context blocks to see which blocks stay relevant. Required instructions remain pinned.
CLAIM / EVIDENCE
Enter a claim and evidence you provide to see whether the evidence supports, contradicts, or does not address it. The tool does not search the web.
LAB / 08 · START BUILDING
Call Jev through AI SDK 7’s evaluation interface and read its structured answers directly. Keep the rules that decide your application’s next action in your own TypeScript code.
Read the quickstartimport { experimental_evaluate as evaluate } from 'ai';
const result = await evaluate({
model: 'typesafe-ai/jev',
state: { task, routingContext },
questions: { route, complexity, externalSideEffect },
maxRetries: 0,
});
// Model signal ≠ application authority
const action = applyPolicy(result.answers);LAB / 09 · COMMON QUESTIONS
Jev is an evaluation model from TypeSafe AI, released in September 2026. It reads text or structured data you provide and returns a choice, a score on a defined scale, or a probability for a yes-or-no question. Your application can use those answers to decide what happens next. Jev AI Tools is this independent site for trying it.
Chat models produce text, which an application may need to parse before using. Jev returns a choice, score, or probability directly. It is suited to those defined answer types; use a text-generating model when you need a summary, explanation, or draft.
Yes. You can inspect the sample results without an account. When Live runs are available, anonymous visitors receive 10 trial credits. Live availability also depends on the site's shared service limits.
Use a text-generating model for summaries, rewrites, explanations, code, or open-ended answers. Jev evaluates supplied text or structured data; it does not interpret images. Choice questions allow up to 255 options, and scoring scales have two to ten levels.
LAB / 10 · PUBLIC PROJECTS
These links lead to projects and demos by other authors. This site has not reproduced their results.
Browse the ecosystem