Jev answers defined questions about an input with choices, scores, and probabilities instead of generated prose. This guide explains how it works, what its probabilities mean, where it performs poorly, and how to use its answers in an application.
Who built Jev, and when it launched
Jev was released on 15 September 2026 by TypeSafe AI. TypeSafe’s founder, Diogo Almeida, previously worked at OpenAI on the instruction-following research that led to ChatGPT; he says the company spent two years in stealth before the launch. TypeSafe trained Jev with a method it calls Reinforcement Learning for Calibrated Decisions (RLCD), which targets accurate probabilities rather than answers people prefer. What Jev probabilities mean explains what that does and does not promise.
Where Jev stands in October 2026
On 9 October 2026 TypeSafe announced an $870 million Series A at a $7.5 billion valuation, led by Andreessen Horowitz with Sequoia and DCVC. The company says a third of the Fortune 500 use Jev; that is its own claim, and it has not published the list.
Jev is also no longer the only model of its kind. OpenAI (the Decisions API), Cloudflare (Clef), Microsoft (Microsoft-Decision-1), Perplexity (pplx-decider) and several open-source projects now ship decision models that answer the same question types, some cheaper and some able to read images. Jev itself is unchanged: still jev-1.13.0, text only, at $0.042 per million input tokens. Our Jev alternatives comparison sets them side by side.
Why use Jev for defined answers?
Many applications need a category, yes-or-no estimate, or severity level. A chat model can provide one in prose, but the application then needs to extract the value and handle responses that vary in format.
Constrained decoding and retries can help with formatting, but they still use a text-generating model. Jev returns the requested value directly: you define the options, scoring scale, or statement to evaluate before making the call.
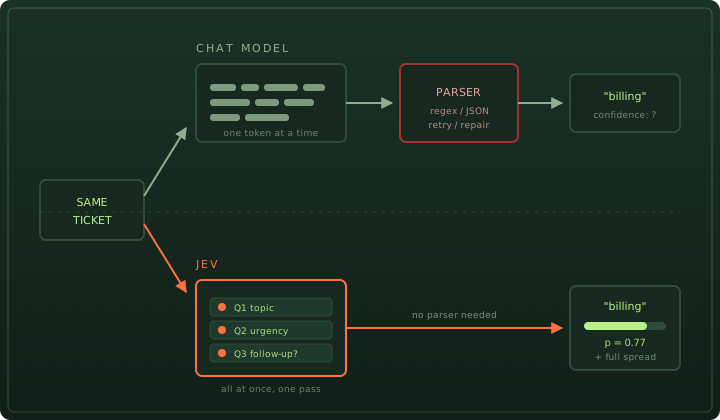
Why it is called a “System One” model
TypeSafe uses the term from Daniel Kahneman’s Thinking, Fast and Slow to describe quick judgments. Jev is designed for defined evaluation questions, such as choosing a route or checking whether a condition appears to hold. It does not generate an explanation of its answer.
For example, an agent may need to choose its next tool, decide whether to ask for clarification, or check whether a goal has been met. Jev can return a signal for those questions; application code still decides what action is allowed.
One state, many questions, one pass
The mechanical difference is that Jev is not autoregressive. A chat model builds its answer one token at a time, each token conditioned on the last, which is why latency scales with output length. Jev takes the state once and evaluates every question against it in parallel, returning everything in a single pass — TypeSafe reports 70–500ms end to end.
Two consequences matter in practice.
Independent questions can share one call. One practitioner measured 13 questions asked together running roughly 10× faster and 12× cheaper than asking them in sequence. Ask the questions you need about the same input together, and measure cost and latency for your own workload.
Questions cannot see each other. Every question is evaluated independently against the same state. Nothing chains. If you need question B to depend on the answer to A, that is two calls with your own logic in between — a real constraint, and the one that most often forces a redesign.
Choice, score, and boolean answers
- Choice — one option from a named set you define, up to 255 of them. You get the selection plus a probability across every candidate. For example,
billing 0.44 / technical 0.41shows that the two categories are close. - Score — a position on an ordered rubric you write in plain language, from 2 to 10 levels. The result can land between levels, because it is a probability-weighted average position rather than a single pick. A 2.5 means the model is split between the second and third rung, not that it found a half-step.
- Boolean — the probability that a statement is true, from 0 to 1. Keep the probability: 0.97 and 0.53 provide different information even if both are converted to
true.
What Jev probabilities mean
Jev was trained with what TypeSafe calls Reinforcement Learning for Calibrated Decisions. Where RLHF optimizes for answers people like, RLCD optimizes for probabilities that match reality: across many predictions, the ones marked 90% should come true about 90% of the time.
That is a claim about aggregates, and it is worth being precise about what it does not say. It does not say any single 0.9 is trustworthy. It does not say the model knows when a question is unanswerable. Calibration is a property of a distribution of predictions, not a guarantee attached to the one in front of you.
TypeSafe has not published how RLCD works or what Jev is built on. Jev architecture and RLCD collects what is public, what isn’t, and how open models copy the approach. For the company itself, see TypeSafe AI.
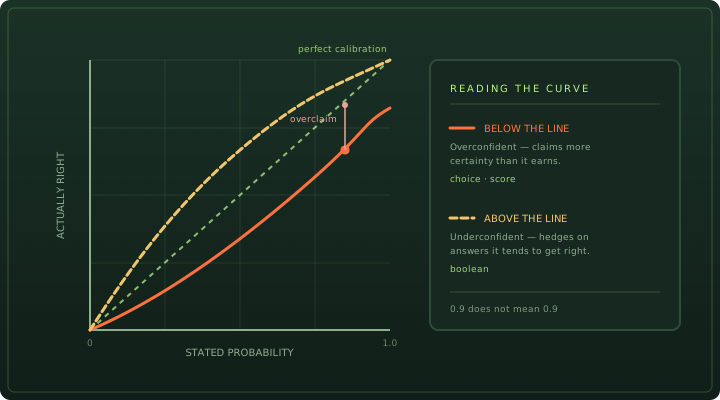
An independent test run shortly after launch makes this concrete. The author generated 900 synthetic support tickets from rules the model could not have seen, asked a choice, a score, and a boolean about each, and published the raw responses. Across 4,621 calls there were zero invalid outputs — the type-safety claim held completely. Calibration was the more interesting result:
- On public benchmarks the probabilities needed almost no correction — though those datasets may well sit inside the training mix.
- On the fresh out-of-distribution tickets, overall error came in at roughly 4× what a perfectly calibrated model would show on the same data.
- The direction of the error differed by question type: choice and score ran overconfident, while boolean ran underconfident. A single threshold applied across all three is therefore wrong in two different directions at once.
The sharpest finding involved a deliberately unanswerable question. Ticket priority depended on a customer-tier rule that appeared nowhere in the ticket text — no reader could have gotten it right. Jev scored 44.7% while assigning its answers an average probability of 0.74. It was confidently wrong on a question nobody could answer, because nothing in the interface lets a model say the state does not contain this.
That is the practical lesson, and it is not really about Jev. A model can only be calibrated over the information you give it. If the deciding fact is missing from the state, high confidence is measuring the wrong thing.
Set thresholds for application actions
Your application can use probability thresholds to send uncertain cases for human review while handling clearer cases under its own rules.
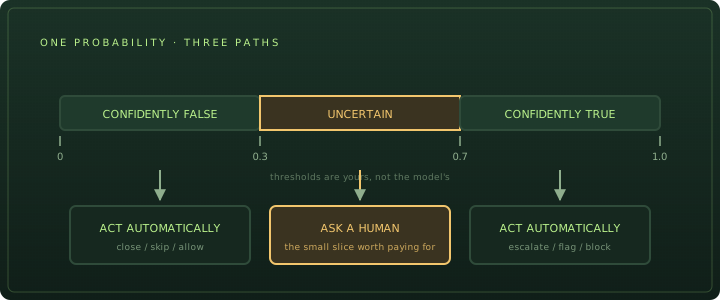
One published spam-classification run illustrates how thresholds can reduce review work. Below 0.1, about 0.1% of messages were spam; above 0.9, about 99.9% were. In the 0.5–0.6 band it was 38%. Sending the uncertain 4.6% of cases to a person lifted overall accuracy to 99.5% in that test.
Notice where the thresholds live. Nothing above is a model setting. The 0.3 and 0.7 are yours, they belong in your code, and tuning them is free because it never calls the model again. The same evaluation can auto-resolve in a low-stakes queue and pause for review in a regulated one.
Tasks Jev handles poorly
Practitioner reports converge on a consistent set of weak spots, and they are specific enough to design around:
- Arithmetic and counting. Do the maths in your code and pass the result, or a bucketed label like
over_limit, into the state. - Dates and time windows. Which came first, whether something falls inside a range — resolve these before the call and hand over a boolean.
- Indirection. Double negatives and deeply nested fields cost accuracy. Point the question straight at the part of the state that matters.
- Irrelevant state. Padding the state with extra context makes answers worse, not safer. Prune first.
- Text generation. Use a text-generating model for summaries, rewrites, code, or explanations.
And the constraint that outranks all of them: a valid answer is not a correct answer. A choice can only return an option you defined, so a wrong one is still perfectly well-typed. Zero type errors and zero schema hallucinations are guarantees about form. Semantic correctness is still yours to verify.
How to read performance claims
TypeSafe reports up to 193.6× faster and 444.6× cheaper performance in its own workflow benchmarks. Those are best-case figures from the vendor, not results from this site. On the four-workflow benchmark, Jev reaches around 68% agreement; the reference answers were produced by other models rather than people. The vendor’s “0% hallucination” figure concerns output format, not whether an answer is correct.
Independent tests reported 96% versus 86% for a small model on listing moderation at a fraction of the cost, and a statistical tie with a logistic-regression classifier trained on roughly 14,800 labelled examples. These are early, small samples. Test accuracy, cost, and latency on your own data before relying on the results.
How to test Jev before using it in production
- Bound the state. One inspectable object, pruned to what the question needs, with anything numeric or temporal resolved in advance.
- Group independent questions. Ask questions about the same input together when they do not depend on each other.
- Calibrate per question type. Collect a few hundred labelled outcomes for each question and find your own thresholds. Do not inherit 0.9 from a blog post — the independent data says it means different things for boolean than for choice.
- Shadow before you switch. Log Jev’s answers next to your existing logic without acting on them. Disagreements are where you learn whether your rubric is the problem.
- Version the whole bundle. Model, questions, criteria, and thresholds move together. Changing a single word of a rubric changes the distribution, so replay a fixed set of inputs whenever any of it changes.
When Jev is a good fit
Jev is a possible fit when the answer has a defined type, the question is asked often enough for latency or cost to matter, and your application can use the answer without a generated explanation. Otherwise, consider a text-generating model, a classifier, or a rule.
Jev returns an evaluation signal. Your code sets the thresholds and decides what action, if any, the application takes. Check those rules and thresholds against outcomes from your own use case.
Try task routing Read the Jev AI API guide
Sources
- TypeSafe AI Introducing System One Models & Jev ↗
- TypeSafe AI TypeSafe A raises Series AI ↗
- TypeSafe docs System One concepts ↗
- Vercel Jev and the AI SDK ↗
- GitHub Independent out-of-distribution calibration test (900 tickets, raw data published) ↗
- Arize Jev versus LLM judges, with third-party results ↗
- Flavio Copes A practitioner’s deep dive ↗
Vendor performance figures are reported as the vendor’s own; independent results are attributed to their authors. This site is not affiliated with TypeSafe AI.